Questions for Exploration: Human Intelligence and AI
Open questions about thought, learning, and the evolution of intelligence, organized with related articles, papers and projects.
Questions for Exploration: Human Intelligence and AI
Open questions about thought, learning, and the evolution of intelligence, organized with related articles, papers and projects.
A hash function converts arbitrary input data into a fixed-size digest.
1 | "hello" |
Important properties:
Blockchains use hashes for transaction IDs, block linking, Merkle trees, and data integrity.
Java Atlas for Full-Stack Engineers
Primitive types store raw values, while wrapper types are objects that can be null and are required by generics/collections.
1 | int age = 18; |
<article>, <section>, <nav>, <header>, <h1><h2> etc.)<title> and <meta name="description" content="xxx"> for each page.<alt> Attributes on Images<meta name="robots"> or robots.txt to control indexing.DOM + CSSOM => Render Tree
Layout(Size, Position) => Paint(Color, Background) => Composite
Recalculate Style => Reflow => Repaint => Compositing
About Machine Learning ( Part 10: Reinforcement Learning )
Reinforcement Learning (RL) is a fascinating branch of machine learning where an agent learns to interact with an environment to maximize long-term cumulative rewards. Unlike supervised learning, RL relies on feedback through interaction instead of labeled data.
The core of RL is built upon Markov Decision Processes (MDPs), which provide a mathematical framework for modeling decision-making under uncertainty.
This blog post explores the key components of RL, including value functions, Q-functions, the Bellman equation, Actor-Critic architectures, PPO, and commonly used tools in real-world RL implementations.
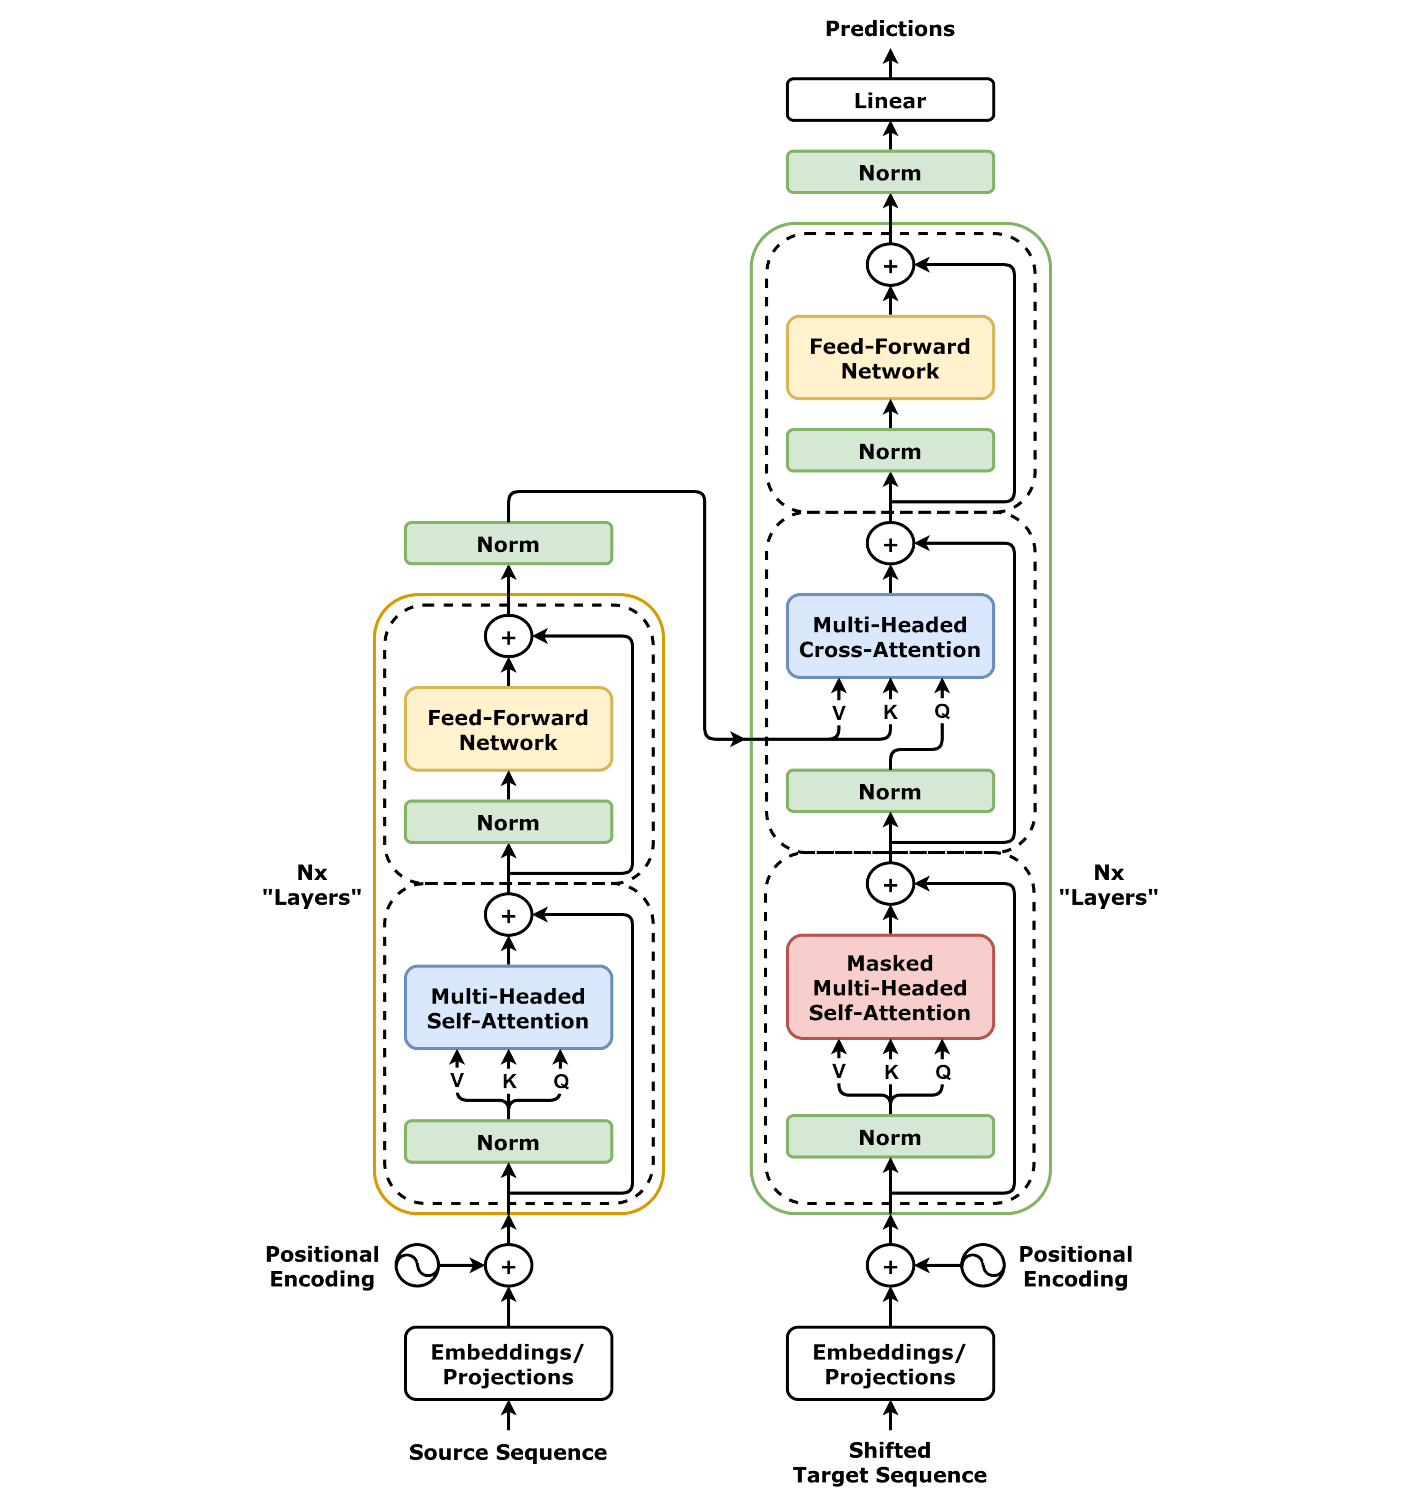
Transformer ( Part 3: Transformer Architecture )
The Transformer consists of two main parts: an encoder and a decoder. They are connected by Cross-Attention.
The Transformer Architecture:
Transformer ( Part 2: Multi-Head Attention )
Before the Transformer, sequence models like RNNs and LSTMs suffered from long-term dependency issues and low parallelization efficiency. Self-Attention was introduced as an alternative, allowing for parallel computation and capturing long-range dependencies.
However, a single-head Self-Attention mechanism has a limitation:
It can only focus on one type of relationship or pattern in the data.
Multi-Head Attention overcomes this by using multiple attention heads that capture different aspects of the input, improving the model’s expressiveness.
About Machine Learning ( Part 9: Recurrent Neural Network )
Recurrent Neural Networks (RNNs) are a class of neural networks designed for sequential data, making them highly effective for tasks like natural language processing (NLP), time series prediction, and speech recognition. Unlike traditional feedforward networks, RNNs maintain a hidden state that captures temporal dependencies.
A traditional feedforward neural network processes inputs independently. However, for sequential tasks, the order of the data is crucial. RNNs address this by maintaining a memory of previous inputs through hidden states.
About Machine Learning ( Part 8: Convolution Neural Networks )
Convolutional Neural Networks (CNNs) have revolutionized the field of computer vision, enabling significant advancements in image recognition, object detection, and segmentation tasks. This blog will explore the key concepts behind CNNs and their working principles.
A Convolutional Neural Network (CNN) is a type of deep learning model specifically designed for processing structured grid data, such as images. Unlike traditional fully connected neural networks, CNNs leverage convolutional layers to capture spatial hierarchies in the data.